Artificial intelligence
RAG: How to Use Company Documents in an AI Application
Learn how RAG connects AI to internal documents and what to assess in retrieval, permissions, source updates, and answer quality.
A support specialist needs to find out whether a customer can switch plans during their contract term. The rule is in a sales policy, exceptions appear in another document, and an outdated version still shows up in search. An assistant that simply writes well can produce a convincing but incorrect answer.
In our article on Amazon Bedrock, we introduced an assistant that consults documents before answering. That workflow uses RAG, short for retrieval-augmented generation. Here, we look more closely at how it works and the decisions that make it useful in everyday work.
What is RAG?
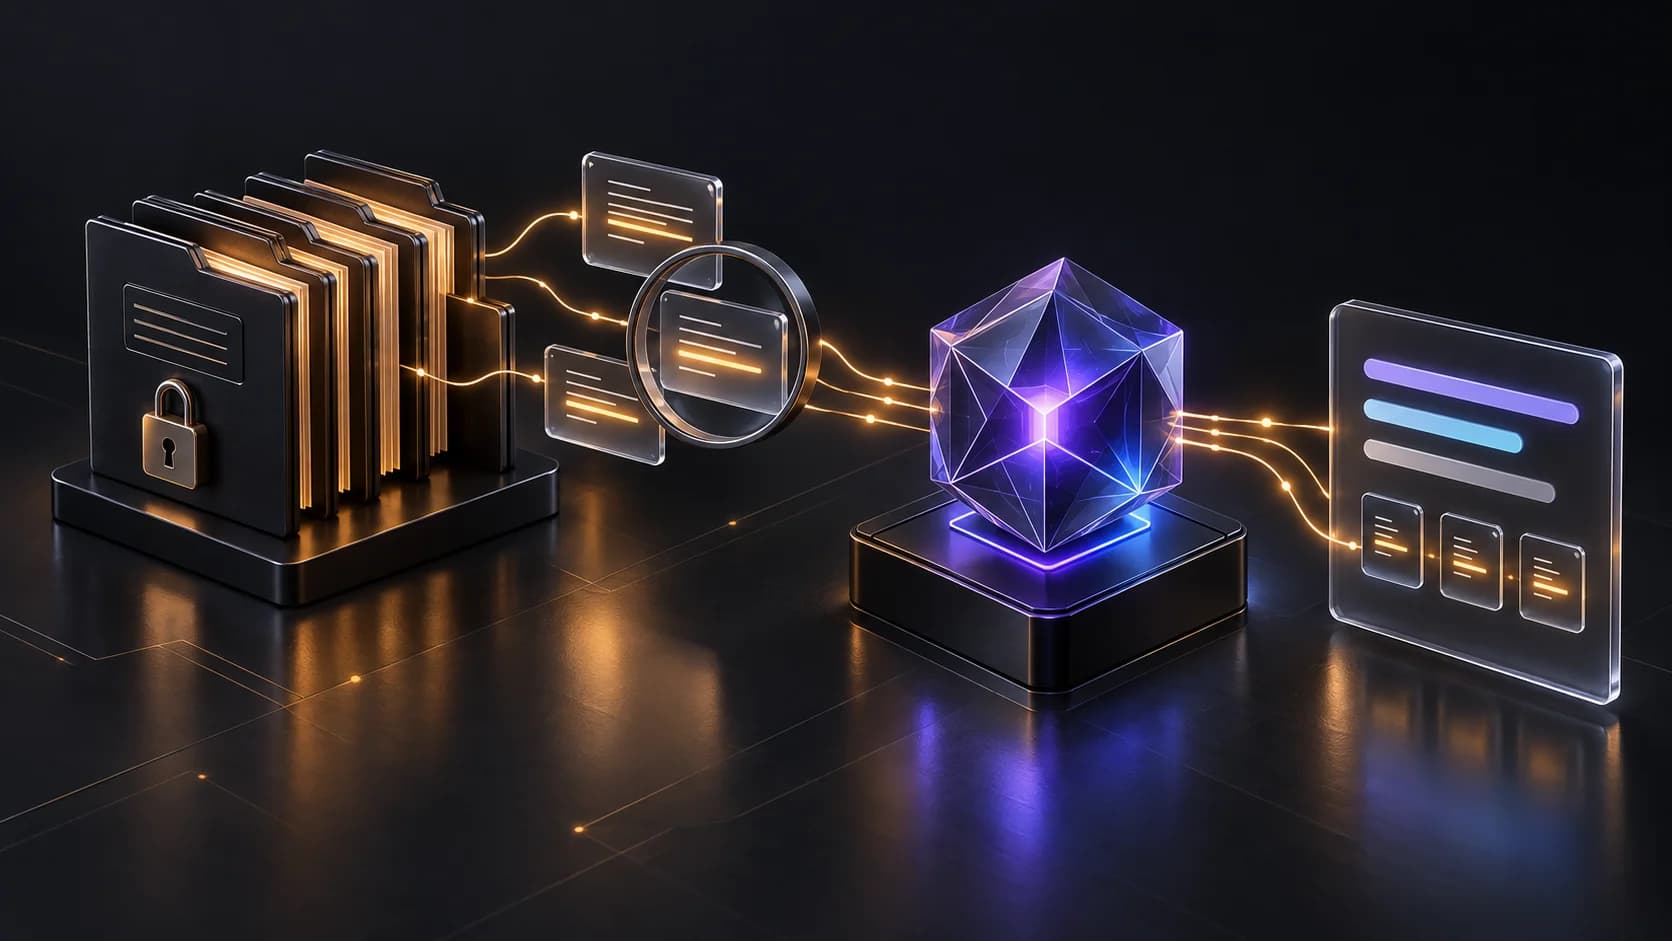
RAG combines information retrieval with answer generation. In an application built around internal documents, the system retrieves passages related to a question and gives them to a model as context. The paper by Lewis and colleagues is a reference for this combination of retrieval and generation.
In this workflow, adding a manual to the knowledge base does not mean retraining the model. Its content is prepared for search and supplied when needed. Sources can therefore change without retraining the model each time, provided the searchable knowledge base is updated too.
RAG helps ground answers in evidence, but it can still retrieve the wrong passage or generate an interpretation the text does not support. Quality depends both on retrieval and on how the model uses the material it receives.
From document to answer: two stages
Work begins before the first question. During knowledge base preparation, the team selects sources, extracts their content, and organizes passages for retrieval. Each passage should retain a connection to its original document, version, and the information needed to decide who may access it.
A common approach uses embeddings: numerical representations of content that allow similarity comparisons. Passages and their references are stored in a search index. The Bedrock documentation on content chunking describes this process and different ways of splitting documents.
At query time, the support assistant could work as follows:
- Identify the specialist and their permissions from the authenticated session.
- Search authorized documents for passages relevant to the question.
- Give the model the question, selected passages, and instructions to answer using those sources.
- Display the answer with references that let the specialist open the document and check the guidance.
- If sources are insufficient or conflicting, ask for clarification or route the question for review.
In our hypothetical example, the current policy allows plan changes at renewal but requires approval from the sales team for immediate changes. A good answer preserves that condition and points to the passage establishing it. If the customer's contract is unavailable, the assistant should make that limitation clear instead of assuming the general rule settles the case.
Retrieval must find the rule and its conditions
Splitting a document into very small chunks can separate a rule from the exception in the next paragraph. Very large chunks can bring in irrelevant material, increase cost, and make the right guidance harder to identify. Test chunking with real questions and check that headings, tables, and conditions remain understandable.
Check content extraction too. A scanned PDF may need optical character recognition; a poorly extracted table may associate a deadline with the wrong plan. Before changing the model, open the retrieved passages and inspect what the application actually supplied to it.
Semantic search helps when a user writes “switch plans” and a document says “contract migration.” Exact terms still matter for product codes or plan names. Bedrock lets you configure search type, filters, and the number of results, depending on your knowledge base configuration. Compare the options against your question set; supplying more passages does not always improve an answer.
Keeping sources current is an operational responsibility
Saving a new policy in a repository does not guarantee the application can already retrieve it. The change must reach the index used for search. In the documented Bedrock synchronization workflow for knowledge bases with vector storage, you need to sync additions, changes, and deletions for those changes to appear in the knowledge base.
Assign an owner to the sources and define an acceptable update delay. For the support assistant, record the version, effective date, applicable product, and time of the last successful sync. A file modified yesterday might contain a rule that only takes effect next month.
Also test removal of outdated documents and invalidation of cached answers. If synchronization fails, the team needs to know the assistant may be using stale material. For critical guidance, consider suspending affected answers until the update is confirmed.
Permissions must follow every query
Access to the chat does not imply access to every company document. A specialist may be allowed to read a general manual but have no authorization to see another customer's negotiations.
The system must enforce authorization before sending content to the model. Microsoft's documentation on document-level access control describes approaches that restrict search results according to the querying user's identity and permissions. Your implementation needs to respect the access rules of your data source.
In the application, derive identity from the authenticated session and validate permissions on the server. Do not rely on a customer identifier freely supplied by the browser or on an instruction such as “do not show confidential data” to protect material the model has already received.
Include users from different teams, revoked access, and documents without defined permissions in your tests. Apply the same protection to source links, conversation history, diagnostic logs, and caches. An answer created for an authorized user must not be reused for someone else without checking access.
How to evaluate answers and check references
Build a question set with the team that knows the documents. For each case, record the expected guidance, the passages supporting it, and who may access them. Include ambiguous questions, conflicting sources, and situations where no answer is available.
Evaluate retrieval first: did the search return the current rule, its conditions, and only authorized content? Then evaluate the answer: did it preserve those conditions, address the question, and avoid adding unsupported information?
A clickable reference is not enough. Open the source and check whether the cited passage supports the claim, belongs to the correct version, and is accessible to the user. In the plan-change example, citing the general policy while omitting the requirement for sales approval is still an error.
| Test case | Expected behavior |
|---|---|
| Question about an immediate plan change | Explain the approval requirement and cite the current rule. |
| Question that does not identify the current plan | Ask for the missing detail before selecting a plan-specific rule. |
| Old and current policies in the knowledge base | Use the version applicable to the date and case being considered. |
| Undocumented exception | State that there is insufficient evidence and route the question for review. |
| Another customer's document | Prevent its content from entering the context or appearing in the answer. |
Measure the share of correct, source-supported answers, the frequency of human corrections, response time, and cost per query. Check whether the system recognizes missing evidence too. Repeat the cases when documents, retrieval, models, or instructions change; an improvement on common questions can make exception handling worse.
When is RAG worthwhile, and how should you start?
RAG can help when a team needs to consult several sources and combine information into an answer. For a balance lookup, a contractual calculation, or a deterministic rule, query the responsible system and execute the appropriate logic. Retrieved text can explain a rule, but it cannot replace the current state of a transaction.
If your company already uses AWS, Amazon Bedrock Knowledge Bases provides retrieval and generation features with source references. A managed service removes some infrastructure work; source selection, access rules, and acceptance criteria remain application decisions.
Start with a narrow task, gather approved documents, and establish a baseline for the current process. Run the pilot with human review and compare total handling time, including checking and correcting answers. Add up document preparation, storage, retrieval, and generation costs.
If the application API or other pilot components run on Linux servers, the VPS and cloud pricing comparator helps assess CPU and memory configurations across providers. This reference covers the selected servers; AI services, vector databases, storage and transfer must be included separately in the project’s cost estimate.
Expand usage when the pilot shows a measurable benefit and the team can manage updates, permissions, and failures. If retrieval misses the right sources or specialists need to rewrite almost every answer, improve those stages before adding more documents.
How Fidalgo IT Solutions can help
Fidalgo IT Solutions can help your team organize sources, connect an assistant to existing systems, and build a RAG pilot with evaluation criteria. We can also review permissions, knowledge base updates, and operating costs so that any decision to expand rests on results observed in real work.
Explore our Artificial Intelligence services for business to understand possible deliverables and how to begin an assessment with your team.